The Instrument Moves: Unrecorded Serving Changes in Agent Benchmarks
Jingyuan Yi · Poster, NeurIPS 2026 workshop Who Verifies the Agents?
We pinned every control a mobile-agent benchmark exposes: model identifier, serving provider, quantization, temperature=0, seed, container image digest, task-set commit, a fresh container per repetition, serial execution. Then we ran the same agent on the same 29 tasks ten times.
What we found
temperature=0 with a fixed seed did not produce determinism on either endpoint we tried. Our first check said otherwise: a short prompt came back byte-identical twice, on an endpoint that turned out not to be deterministic.
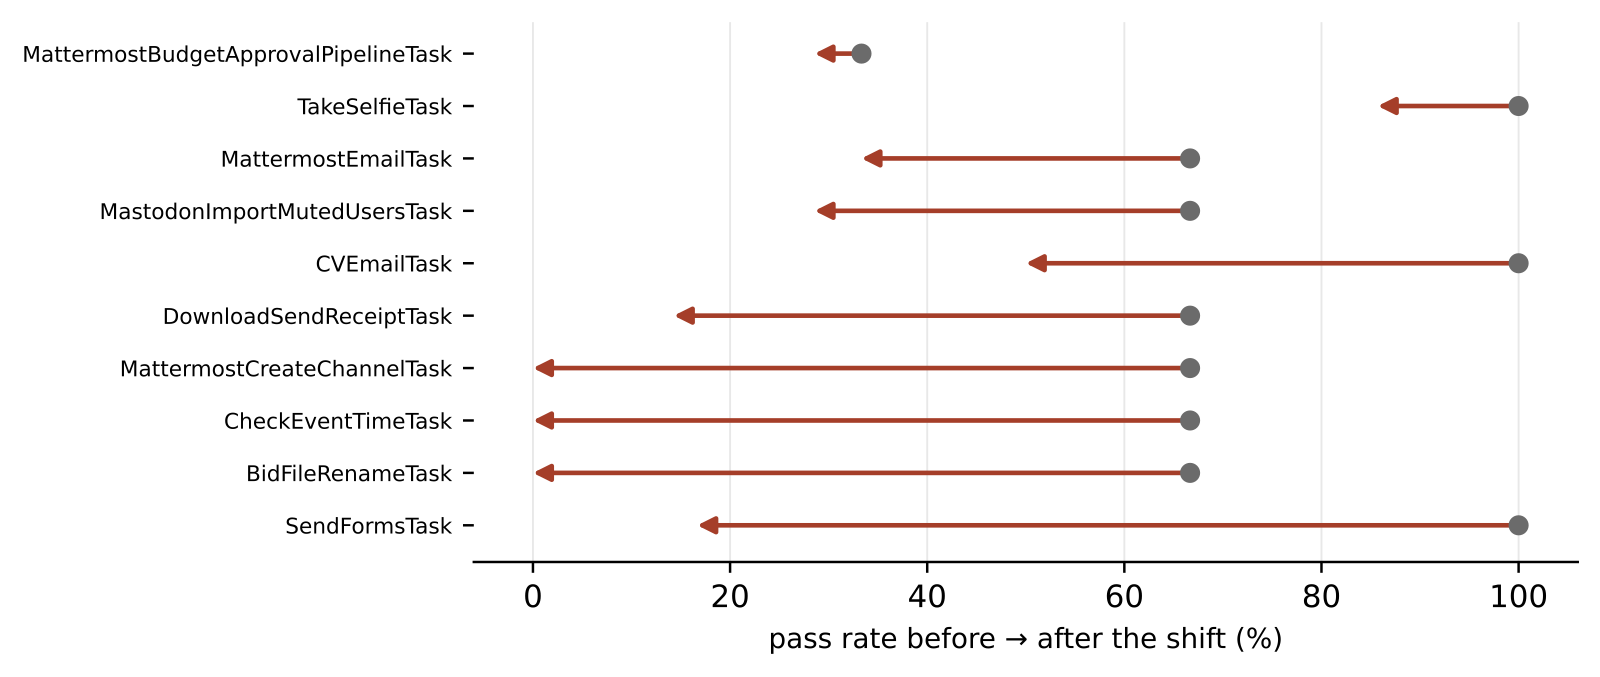
Ten and a half hours in, the pinned endpoint’s behaviour changed. Ten tasks got worse and none got better. Median completion tokens per action fell by a fifth at a single round boundary and stayed there. We observed the endpoint’s behaviour, not its configuration: the shift was specific to that endpoint, absent from a control, and invisible to every field a leaderboard records.
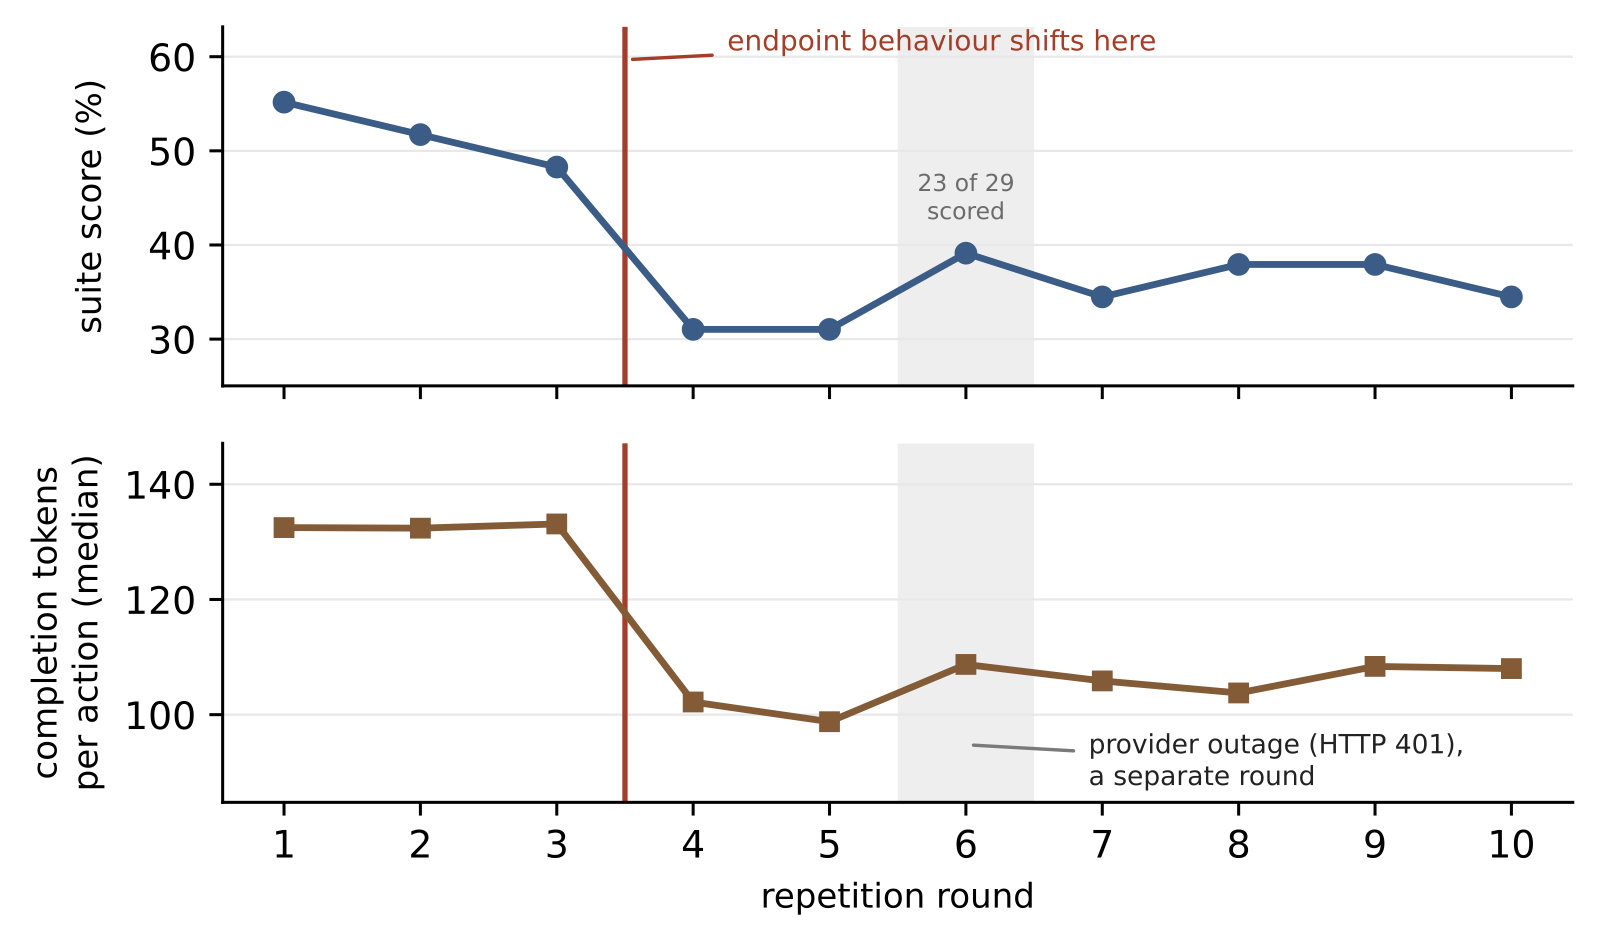
Two single-run scores need to differ by roughly eight points before the gap exceeds what repetition alone produces, for this agent, this endpoint and this reweighted task sample. The exact figure is 8.07; resampling whole rounds gives a 95% interval of 5.18–8.53.
The token signal flagged the shift at the round level; the score did not. The signal costs one integer per request to log. It has worked once, after the fact, so we offer it as a side signal and not as a validated detector.
Since the paper
Since 4 September the endpoint sentinel has sent the paper’s determinism probe, unchanged, to the paper’s pinned endpoint and to thirteen others, every day. Two things it has recorded bear directly on the paper:
- The paper’s control endpoint, DeepInfra’s fp4 Kimi K2.5, stopped being served on 8 September. That arm of the paper can no longer be rerun as recorded.
- The pinned endpoint, AtlasCloud’s int4 Kimi K2.5, raised no length alarm from 6 to 29 September.
Over the same weeks, three of the eight providers that listed Kimi K2.5 in early September stopped serving it.
What is released
Every run (314 rows, each with the full configuration it ran under), the analysis that reproduces every number in the paper, a script that checks the paper’s numbers against the data, and notes on what the benchmark’s harness actually does. The daily endpoint sentinel grew out of this paper; its false-alarm record is part of the release.
Corrections
Differences from the version submitted for review. No finding depends on any of them.
- A pass over the benchmark’s published trajectory bundles found that our parser under-read three of the eighteen. Runs stopped at the 50-step cap are 490 zeros and 35 passes, not 407 zeros and 90 unscored, and the pilot task groups were assigned from 15 of the 18 bundles.
- The threshold is now computed exactly: 8.07 points. The submitted 8.15 came from simulation noise.
- The verifier audit covered six tasks, not five. It found no false positives or false negatives, one task whose scoring rejects correct answers (it did not affect our runs), and one case that remains open.
Cite
@misc{yi2026instrument,
  title         = {The Instrument Moves: Unrecorded Serving Changes in Agent Benchmarks},
  author        = {Yi, Jingyuan},
  year          = {2026},
  url           = {https://github.com/Universeyi/instrument-moves}
}