I measure the instruments that measure AI agents. A benchmark is an instrument; it has a noise floor, it drifts, and current reporting practice has no field that would show either. I build the small pieces that make those visible: a probe that runs every day, a format for recording what produced a number, and the analysis that reads a leaderboard against its own noise.

Poster, NeurIPS 2026 workshop "Who Verifies the Agents?"

The Instrument Moves: Unrecorded Serving Changes in Agent Benchmarks

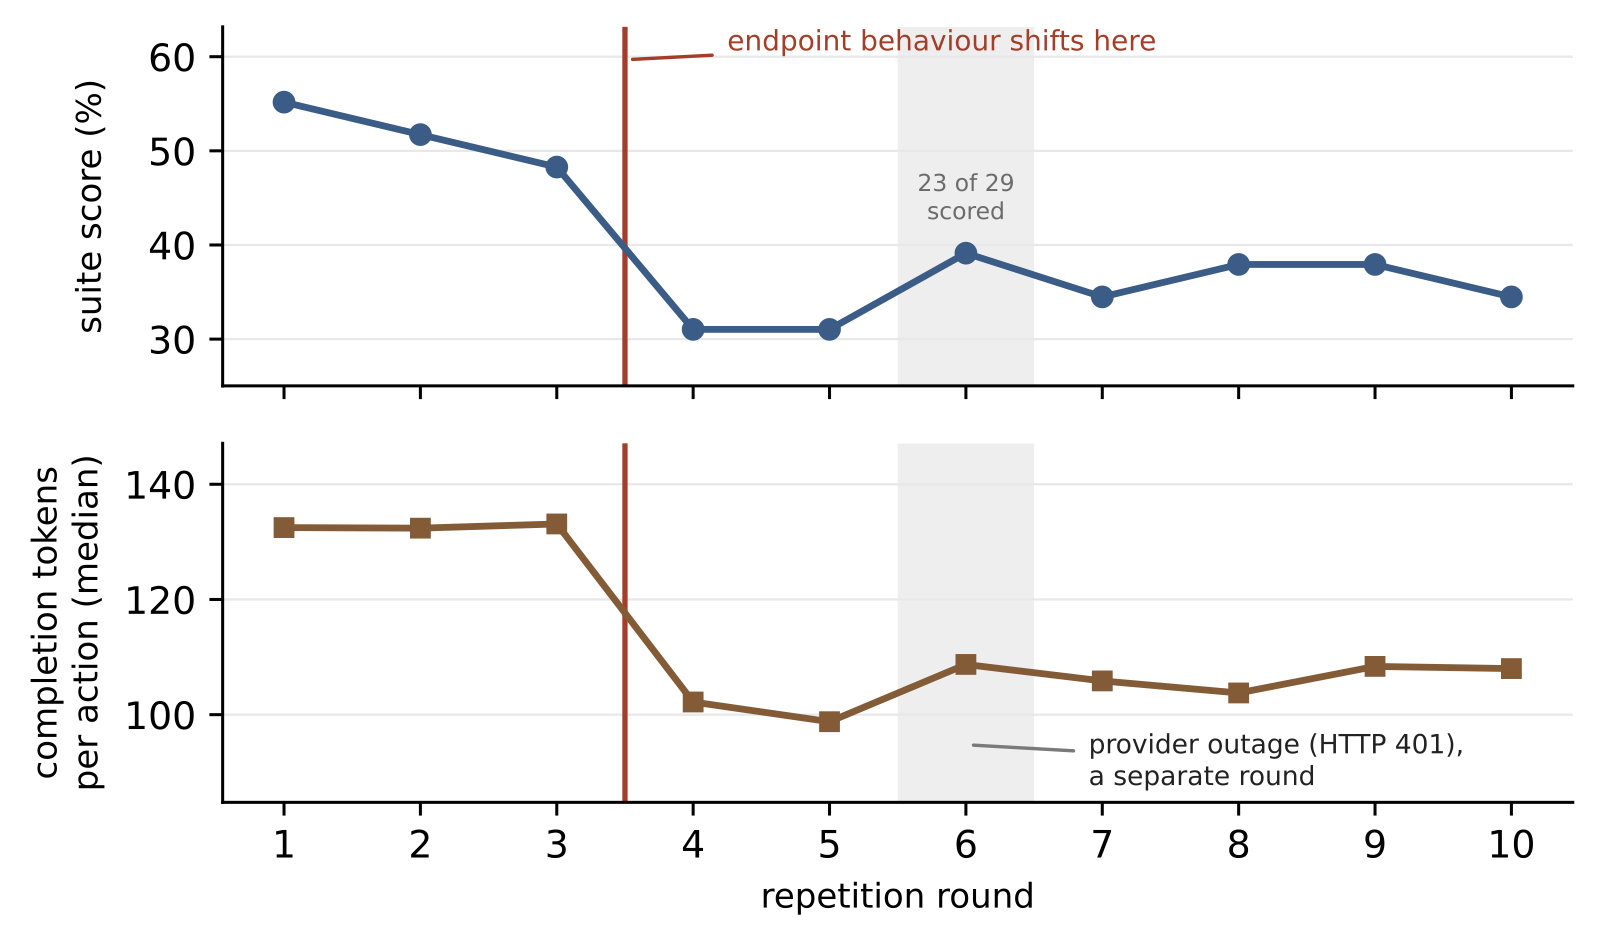
We pinned every control a mobile-agent benchmark exposes and ran ten repetitions. Ten and a half hours in, the pinned endpoint's behaviour changed, and no field a leaderboard records would have shown it.

10 of 10
tasks that changed got worse
−20%
completion tokens per action, in one step
~8 pt
gap two single runs need to exceed noise
Read the paper Code and data

Suite score and completion tokens per action across ten rounds; both step down between rounds 3 and 4

The sentinel sends the paper's probe, every day, to the paper's endpoint and to thirteen others.

live since 2026-09-04

Endpoint sentinel

The same fixed probe, every day, against hosted inference endpoints: determinism, output length, latency, served provider, and step changes.

Daily median output length of the paper's pinned endpoint (Kimi K2.5 on AtlasCloud int4).
  • DeepInfra stopped serving Kimi K2.5 (fp4), the paper's control endpoint
  • DeepInfra's bf16 gpt-oss-120b returned the same completion most of the time for four days, then went back to varying
  • Phala stopped serving Kimi K2.5: three providers gone in ten days

Open the dashboard

Open source · v0.1.0

evidence-manifest

A small record of what produced a benchmark number. Run on the repeated runs eight public benchmarks publish, it gives each one's noise floor.

Noise floors for eight benchmarksGitHub

Writing